# AI settings cannot load model list
**URL:** https://discourse.devontechnologies.com/t/ai-settings-cannot-load-model-list/87673
**Category:** Artificial Intelligence
**Created:** [September 19, 2026, 5:18am UTC](https://discourse.devontechnologies.com/t/ai-settings-cannot-load-model-list/87673 "2026-09-19T05:18:01Z")
**Posts on this page:** 7
**Page:** 1
### Author:  [@SopShuttle](https://discourse.devontechnologies.com/u/SopShuttle)
#### Post date: [September 19, 2026, 5:18am UTC](https://discourse.devontechnologies.com/t/ai-settings-cannot-load-model-list/87673/1 "2026-09-19T05:18:01Z")
Versions:
- DEVONthink 4.3.2 Pro Edition
- lllama.cpp 0.42.0
I had been using this setup for a few months, but recently it has stopped working and I cannot figure out why. When I set the AI provider settings, the Model list will not load.
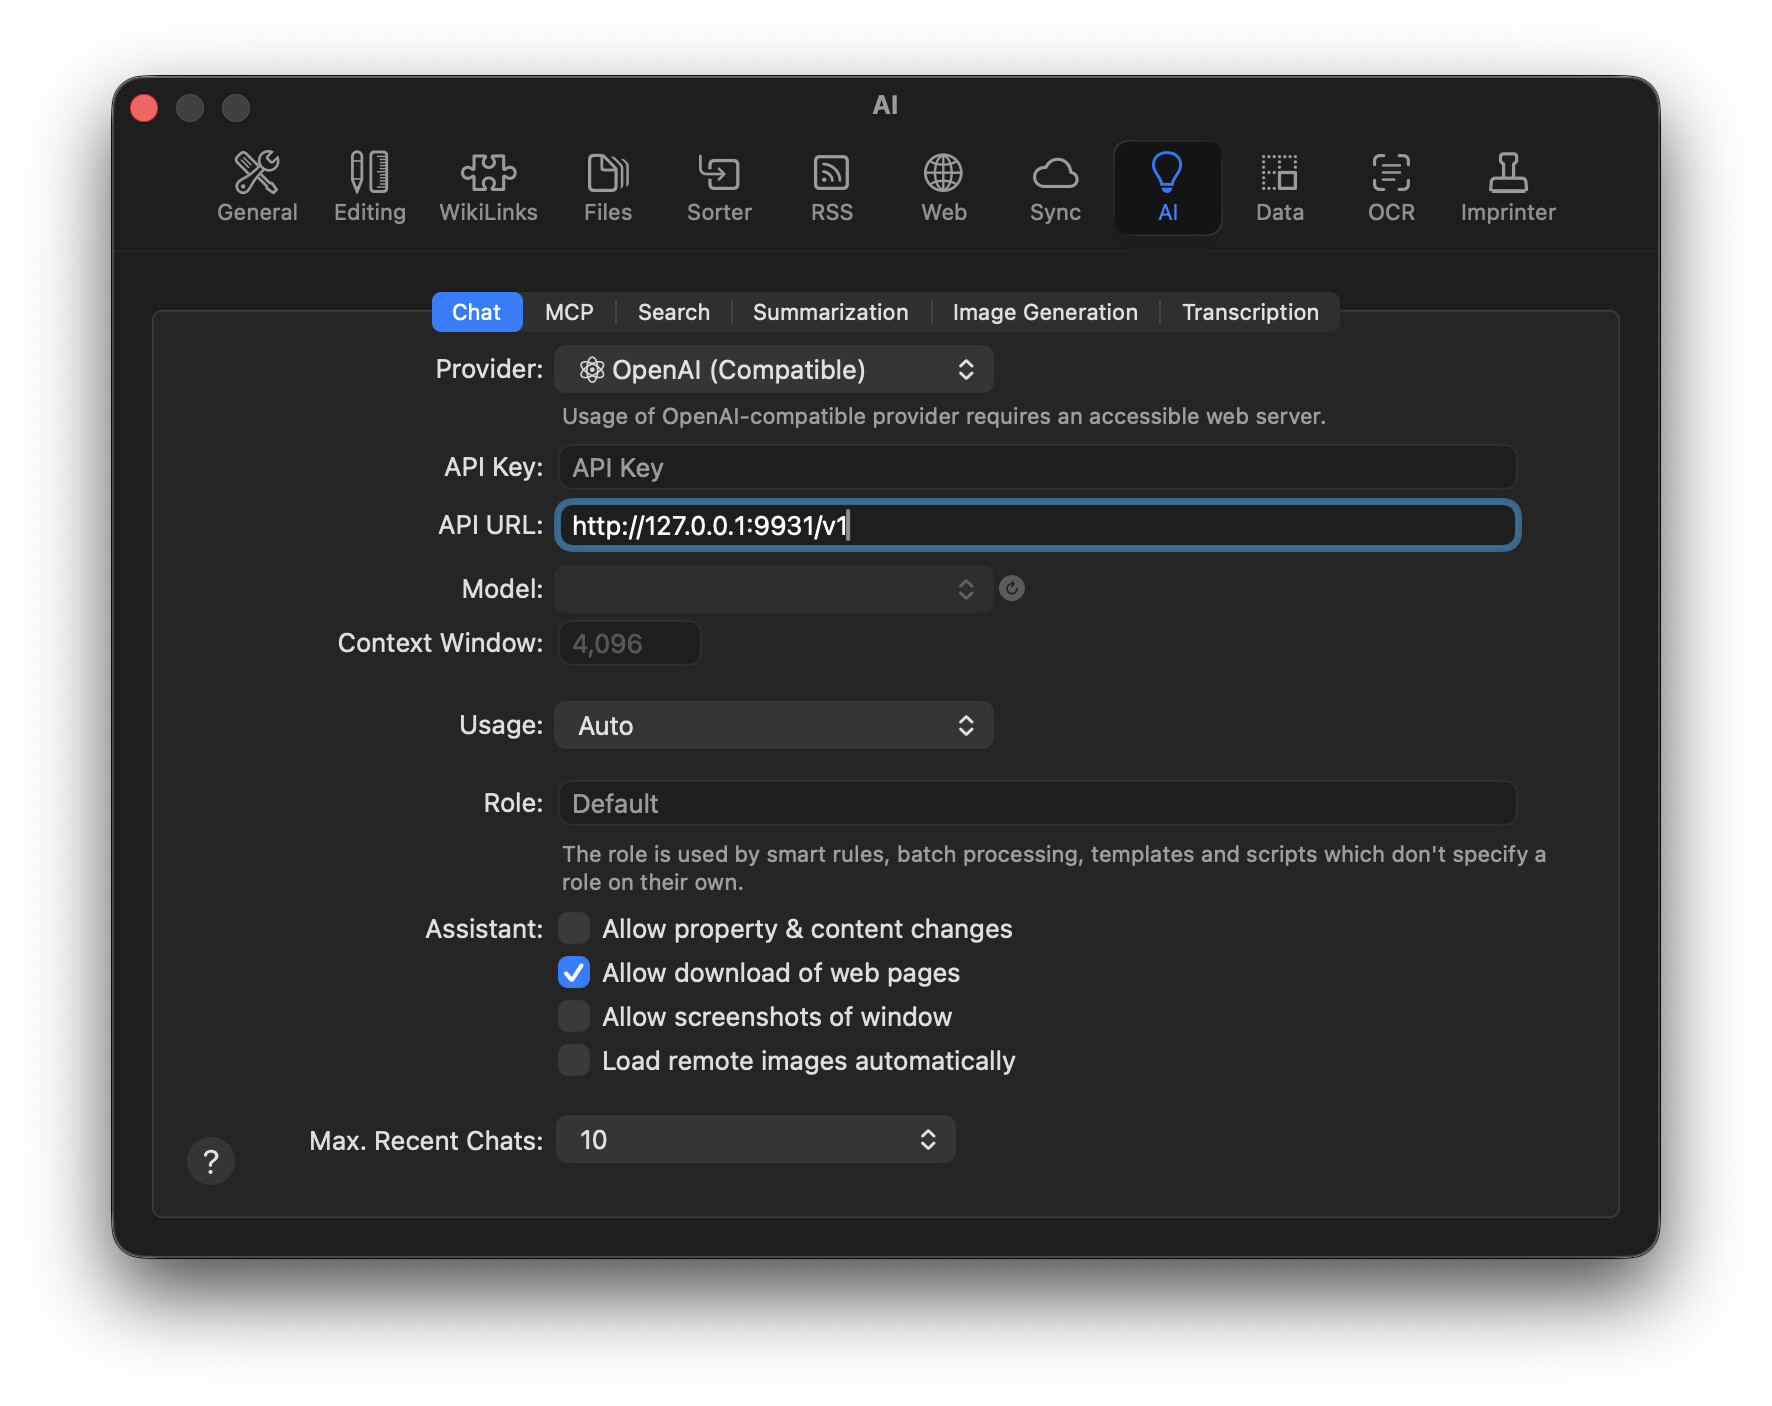
I know the endpoint is working because I can reach it from the command line:
```auto
❯ curl -s http://localhost:9931/models | jq
{
"data": [
{
"id": "ggml-org/Qwen2.5-Coder-1.5B-Instruct-Q8_0-GGUF:Q8_0",
"aliases": [],
"tags": [],
"object": "model",
"owned_by": "llamacpp",
"created": 1789794791,
"status": {
"value": "unloaded",
"args": [
"/Users/sop/.llama-app/llama",
"serve",
"--host",
"127.0.0.1",
"--jinja",
"--log-file",
"/tmp/llama-server.log",
"--port",
"0",
"--sleep-idle-seconds",
"900",
"--spec-default",
"--alias",
"ggml-org/Qwen2.5-Coder-1.5B-Instruct-Q8_0-GGUF:Q8_0",
"--ctx-size",
"4096",
"--fit-target",
"1024",
"--model",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen2.5-Coder-1.5B-Instruct-Q8_0-GGUF/snapshots/9a02a57656dad824ae12a0a2d625d85e9646cc84/qwen2.5-coder-1.5b-instruct-q8_0.gguf",
"--ubatch-size",
"2048"
],
"preset": "[ggml-org/Qwen2.5-Coder-1.5B-Instruct-Q8_0-GGUF:Q8_0]\njinja = 1\nlog-file = /tmp/llama-server.log\nsleep-idle-seconds = 900\nspec-default = 1\nctx-size = 4096\nfit-target = 1024\nmodel = /Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen2.5-Coder-1.5B-Instruct-Q8_0-GGUF/snapshots/9a02a57656dad824ae12a0a2d625d85e9646cc84/qwen2.5-coder-1.5b-instruct-q8_0.gguf\nubatch-size = 2048\n\n"
},
"architecture": {
"input_modalities": [
"text"
],
"output_modalities": [
"text"
]
},
"source": "preset",
"can_remove": false
},
{
"id": "ggml-org/Qwen2.5-Coder-1.5B-Q8_0-GGUF:Q8_0",
"aliases": [],
"tags": [],
"object": "model",
"owned_by": "llamacpp",
"created": 1789794791,
"status": {
"value": "unloaded",
"args": [
"/Users/sop/.llama-app/llama",
"serve",
"--host",
"127.0.0.1",
"--jinja",
"--log-file",
"/tmp/llama-server.log",
"--port",
"0",
"--sleep-idle-seconds",
"900",
"--spec-default",
"--alias",
"ggml-org/Qwen2.5-Coder-1.5B-Q8_0-GGUF:Q8_0",
"--ctx-size",
"4096",
"--fit-target",
"1024",
"--model",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen2.5-Coder-1.5B-Q8_0-GGUF/snapshots/8be1b8a895a84beea772817caaa71eba6b6e0d07/qwen2.5-coder-1.5b-q8_0.gguf",
"--ubatch-size",
"2048"
],
"preset": "[ggml-org/Qwen2.5-Coder-1.5B-Q8_0-GGUF:Q8_0]\njinja = 1\nlog-file = /tmp/llama-server.log\nsleep-idle-seconds = 900\nspec-default = 1\nctx-size = 4096\nfit-target = 1024\nmodel = /Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen2.5-Coder-1.5B-Q8_0-GGUF/snapshots/8be1b8a895a84beea772817caaa71eba6b6e0d07/qwen2.5-coder-1.5b-q8_0.gguf\nubatch-size = 2048\n\n"
},
"architecture": {
"input_modalities": [
"text"
],
"output_modalities": [
"text"
]
},
"source": "preset",
"can_remove": false
},
{
"id": "ggml-org/Qwen2.5-Coder-3B-Instruct-Q8_0-GGUF:Q8_0",
"aliases": [],
"tags": [],
"object": "model",
"owned_by": "llamacpp",
"created": 1789794791,
"status": {
"value": "unloaded",
"args": [
"/Users/sop/.llama-app/llama",
"serve",
"--host",
"127.0.0.1",
"--jinja",
"--log-file",
"/tmp/llama-server.log",
"--port",
"0",
"--sleep-idle-seconds",
"900",
"--spec-default",
"--alias",
"ggml-org/Qwen2.5-Coder-3B-Instruct-Q8_0-GGUF:Q8_0",
"--ctx-size",
"32768",
"--fit-target",
"1024",
"--model",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen2.5-Coder-3B-Instruct-Q8_0-GGUF/snapshots/4944a3e9ecbaacda76873e9577d038400413772c/qwen2.5-coder-3b-instruct-q8_0.gguf",
"--ubatch-size",
"2048"
],
"preset": "[ggml-org/Qwen2.5-Coder-3B-Instruct-Q8_0-GGUF:Q8_0]\njinja = 1\nlog-file = /tmp/llama-server.log\nsleep-idle-seconds = 900\nspec-default = 1\nctx-size = 32768\nfit-target = 1024\nmodel = /Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen2.5-Coder-3B-Instruct-Q8_0-GGUF/snapshots/4944a3e9ecbaacda76873e9577d038400413772c/qwen2.5-coder-3b-instruct-q8_0.gguf\nubatch-size = 2048\n\n"
},
"architecture": {
"input_modalities": [
"text"
],
"output_modalities": [
"text"
]
},
"source": "preset",
"can_remove": false
},
{
"id": "ggml-org/Qwen2.5-Coder-3B-Q8_0-GGUF:Q8_0",
"aliases": [],
"tags": [],
"object": "model",
"owned_by": "llamacpp",
"created": 1789794791,
"status": {
"value": "unloaded",
"args": [
"/Users/sop/.llama-app/llama",
"serve",
"--host",
"127.0.0.1",
"--jinja",
"--log-file",
"/tmp/llama-server.log",
"--port",
"0",
"--sleep-idle-seconds",
"900",
"--spec-default",
"--alias",
"ggml-org/Qwen2.5-Coder-3B-Q8_0-GGUF:Q8_0",
"--ctx-size",
"4096",
"--fit-target",
"1024",
"--model",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen2.5-Coder-3B-Q8_0-GGUF/snapshots/9c1de162ae417c9c3aacde97c729c4128de047d8/qwen2.5-coder-3b-q8_0.gguf",
"--ubatch-size",
"2048"
],
"preset": "[ggml-org/Qwen2.5-Coder-3B-Q8_0-GGUF:Q8_0]\njinja = 1\nlog-file = /tmp/llama-server.log\nsleep-idle-seconds = 900\nspec-default = 1\nctx-size = 4096\nfit-target = 1024\nmodel = /Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen2.5-Coder-3B-Q8_0-GGUF/snapshots/9c1de162ae417c9c3aacde97c729c4128de047d8/qwen2.5-coder-3b-q8_0.gguf\nubatch-size = 2048\n\n"
},
"architecture": {
"input_modalities": [
"text"
],
"output_modalities": [
"text"
]
},
"source": "preset",
"can_remove": false
},
{
"id": "ggml-org/Qwen3.8-27B-GGUF:Q8_0",
"aliases": [],
"tags": [],
"object": "model",
"owned_by": "llamacpp",
"created": 1789794791,
"status": {
"value": "unloaded",
"args": [
"/Users/sop/.llama-app/llama",
"serve",
"--host",
"127.0.0.1",
"--jinja",
"--log-file",
"/tmp/llama-server.log",
"--port",
"0",
"--sleep-idle-seconds",
"900",
"--spec-default",
"--model-draft",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen3.8-27B-GGUF/snapshots/0669b98607d47046c7c2b3f801011d54a08cfccf/mtp-Qwen3.8-27B-Q8_0.gguf",
"--spec-draft-n-max",
"3",
"--spec-type",
"draft-mtp",
"--alias",
"ggml-org/Qwen3.8-27B-GGUF:Q8_0",
"--ctx-size",
"32768",
"--fit-target",
"1024",
"--model",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen3.8-27B-GGUF/snapshots/0669b98607d47046c7c2b3f801011d54a08cfccf/Qwen3.8-27B-Q8_0.gguf",
"--mmproj",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen3.8-27B-GGUF/snapshots/0669b98607d47046c7c2b3f801011d54a08cfccf/mmproj-Qwen3.8-27B-Q8_0.gguf",
"--ubatch-size",
"2048"
],
"preset": "[ggml-org/Qwen3.8-27B-GGUF:Q8_0]\njinja = 1\nlog-file = /tmp/llama-server.log\nsleep-idle-seconds = 900\nspec-default = 1\nmodel-draft = /Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen3.8-27B-GGUF/snapshots/0669b98607d47046c7c2b3f801011d54a08cfccf/mtp-Qwen3.8-27B-Q8_0.gguf\nspec-draft-n-max = 3\nspec-type = draft-mtp\nctx-size = 32768\nfit-target = 1024\nmodel = /Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen3.8-27B-GGUF/snapshots/0669b98607d47046c7c2b3f801011d54a08cfccf/Qwen3.8-27B-Q8_0.gguf\nmmproj = /Users/sop/.cache/huggingface/hub/models--ggml-org--Qwen3.8-27B-GGUF/snapshots/0669b98607d47046c7c2b3f801011d54a08cfccf/mmproj-Qwen3.8-27B-Q8_0.gguf\nubatch-size = 2048\n\n"
},
"architecture": {
"input_modalities": [
"text",
"image"
],
"output_modalities": [
"text"
]
},
"source": "preset",
"can_remove": false
},
{
"id": "ggml-org/gemma-4-12B-it-GGUF:Q8_0",
"aliases": [],
"tags": [],
"object": "model",
"owned_by": "llamacpp",
"created": 1789794791,
"status": {
"value": "loaded",
"args": [
"/Users/sop/.llama-app/llama",
"serve",
"--host",
"127.0.0.1",
"--jinja",
"--log-file",
"/tmp/llama-server.log",
"--port",
"64962",
"--sleep-idle-seconds",
"900",
"--spec-default",
"--model-draft",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--gemma-4-12B-it-GGUF/snapshots/7e0fbb8205d1f4857f4606a38a65023aaeb5f544/mtp-gemma-4-12B-it-Q8_0.gguf",
"--spec-draft-n-max",
"3",
"--spec-type",
"draft-mtp",
"--alias",
"ggml-org/gemma-4-12B-it-GGUF:Q8_0",
"--ctx-size",
"131072",
"--fit-target",
"1024",
"--model",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--gemma-4-12B-it-GGUF/snapshots/7e0fbb8205d1f4857f4606a38a65023aaeb5f544/gemma-4-12B-it-Q8_0.gguf",
"--mmproj",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--gemma-4-12B-it-GGUF/snapshots/7e0fbb8205d1f4857f4606a38a65023aaeb5f544/mmproj-gemma-4-12B-it-Q8_0.gguf",
"--ubatch-size",
"2048"
],
"preset": "[ggml-org/gemma-4-12B-it-GGUF:Q8_0]\njinja = 1\nlog-file = /tmp/llama-server.log\nsleep-idle-seconds = 900\nspec-default = 1\nmodel-draft = /Users/sop/.cache/huggingface/hub/models--ggml-org--gemma-4-12B-it-GGUF/snapshots/7e0fbb8205d1f4857f4606a38a65023aaeb5f544/mtp-gemma-4-12B-it-Q8_0.gguf\nspec-draft-n-max = 3\nspec-type = draft-mtp\nctx-size = 131072\nfit-target = 1024\nmodel = /Users/sop/.cache/huggingface/hub/models--ggml-org--gemma-4-12B-it-GGUF/snapshots/7e0fbb8205d1f4857f4606a38a65023aaeb5f544/gemma-4-12B-it-Q8_0.gguf\nmmproj = /Users/sop/.cache/huggingface/hub/models--ggml-org--gemma-4-12B-it-GGUF/snapshots/7e0fbb8205d1f4857f4606a38a65023aaeb5f544/mmproj-gemma-4-12B-it-Q8_0.gguf\nubatch-size = 2048\n\n"
},
"architecture": {
"input_modalities": [
"text",
"image",
"audio"
],
"output_modalities": [
"text"
]
},
"source": "preset",
"can_remove": false,
"meta": {
"vocab_type": true,
"n_vocab": 262144,
"n_ctx": 131072,
"n_ctx_train": 262144,
"n_embd": 3840,
"n_params": 11907350576,
"size": 12653822144,
"ftype": "Q8_0"
}
},
{
"id": "ggml-org/gemma-4-26B-A4B-it-GGUF:Q8_0",
"aliases": [],
"tags": [],
"object": "model",
"owned_by": "llamacpp",
"created": 1789794791,
"status": {
"value": "unloaded",
"args": [
"/Users/sop/.llama-app/llama",
"serve",
"--host",
"127.0.0.1",
"--jinja",
"--log-file",
"/tmp/llama-server.log",
"--port",
"0",
"--sleep-idle-seconds",
"900",
"--spec-default",
"--model-draft",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--gemma-4-26B-A4B-it-GGUF/snapshots/bb4531cda34d1ea09d9814959ed4d5833cf2a4c8/mtp-gemma-4-26B-A4B-it-Q8_0.gguf",
"--spec-draft-n-max",
"3",
"--spec-type",
"draft-mtp",
"--alias",
"ggml-org/gemma-4-26B-A4B-it-GGUF:Q8_0",
"--ctx-size",
"65536",
"--fit-target",
"1024",
"--model",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--gemma-4-26B-A4B-it-GGUF/snapshots/bb4531cda34d1ea09d9814959ed4d5833cf2a4c8/gemma-4-26B-A4B-it-Q8_0.gguf",
"--mmproj",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--gemma-4-26B-A4B-it-GGUF/snapshots/bb4531cda34d1ea09d9814959ed4d5833cf2a4c8/mmproj-gemma-4-26B-A4B-it-Q8_0.gguf",
"--ubatch-size",
"2048"
],
"preset": "[ggml-org/gemma-4-26B-A4B-it-GGUF:Q8_0]\njinja = 1\nlog-file = /tmp/llama-server.log\nsleep-idle-seconds = 900\nspec-default = 1\nmodel-draft = /Users/sop/.cache/huggingface/hub/models--ggml-org--gemma-4-26B-A4B-it-GGUF/snapshots/bb4531cda34d1ea09d9814959ed4d5833cf2a4c8/mtp-gemma-4-26B-A4B-it-Q8_0.gguf\nspec-draft-n-max = 3\nspec-type = draft-mtp\nctx-size = 65536\nfit-target = 1024\nmodel = /Users/sop/.cache/huggingface/hub/models--ggml-org--gemma-4-26B-A4B-it-GGUF/snapshots/bb4531cda34d1ea09d9814959ed4d5833cf2a4c8/gemma-4-26B-A4B-it-Q8_0.gguf\nmmproj = /Users/sop/.cache/huggingface/hub/models--ggml-org--gemma-4-26B-A4B-it-GGUF/snapshots/bb4531cda34d1ea09d9814959ed4d5833cf2a4c8/mmproj-gemma-4-26B-A4B-it-Q8_0.gguf\nubatch-size = 2048\n\n"
},
"architecture": {
"input_modalities": [
"text",
"image"
],
"output_modalities": [
"text"
]
},
"source": "preset",
"can_remove": false
},
{
"id": "ggml-org/gpt-oss-20b-GGUF:MXFP4",
"aliases": [],
"tags": [],
"object": "model",
"owned_by": "llamacpp",
"created": 1789794791,
"status": {
"value": "unloaded",
"args": [
"/Users/sop/.llama-app/llama",
"serve",
"--host",
"127.0.0.1",
"--jinja",
"--log-file",
"/tmp/llama-server.log",
"--port",
"0",
"--sleep-idle-seconds",
"900",
"--spec-default",
"--alias",
"ggml-org/gpt-oss-20b-GGUF:MXFP4",
"--ctx-size",
"131072",
"--fit-target",
"1024",
"--model",
"/Users/sop/.cache/huggingface/hub/models--ggml-org--gpt-oss-20b-GGUF/snapshots/ef9b12f2ff56c69cf32153a02784e7a3c88bf524/gpt-oss-20b-MXFP4.gguf",
"--ubatch-size",
"2048"
],
"preset": "[ggml-org/gpt-oss-20b-GGUF:MXFP4]\njinja = 1\nlog-file = /tmp/llama-server.log\nsleep-idle-seconds = 900\nspec-default = 1\nctx-size = 131072\nfit-target = 1024\nmodel = /Users/sop/.cache/huggingface/hub/models--ggml-org--gpt-oss-20b-GGUF/snapshots/ef9b12f2ff56c69cf32153a02784e7a3c88bf524/gpt-oss-20b-MXFP4.gguf\nubatch-size = 2048\n\n"
},
"architecture": {
"input_modalities": [
"text"
],
"output_modalities": [
"text"
]
},
"source": "preset",
"can_remove": false
}
],
"object": "list"
}
```
In `~/Library/Application Support/DEVONthink/Chat.log` I see these messages:
```auto
Loading of models failed: Invalid HTTP status 404
```
(it seems like 1 line like that for each model).
How can I troubleshoot this? I can’t see what request DEVONthink is trying to make when getting this HTTP 404 status response.
---
### Author:  [@cgrunenberg](https://discourse.devontechnologies.com/u/cgrunenberg)
#### Post date: [September 19, 2026, 7:19am UTC](https://discourse.devontechnologies.com/t/ai-settings-cannot-load-model-list/87673/2 "2026-09-19T07:19:52Z")
The URL is incomplete, the suffix `/chat/completions` is required. In this case `http://127.0.0.1:9931/v1/chat/completions`.
The next maintenance release will show an error message in case of incomplete/invalid URLs.
---
### Author:  [@SopShuttle](https://discourse.devontechnologies.com/u/SopShuttle)
#### Post date: [September 19, 2026, 5:28pm UTC](https://discourse.devontechnologies.com/t/ai-settings-cannot-load-model-list/87673/3 "2026-09-19T17:28:51Z")
Thank you @cgrunenberg!
However, that only partially works.
I only see 2 out of my 8 models in the list:
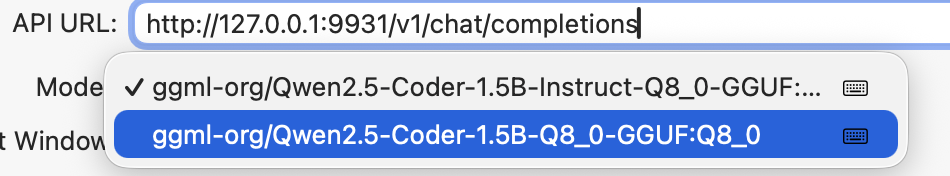
The `Chat.log` shows this when I hit the reload models button:
```auto
2026-09-19 10:28:14,477 ERROR: Loading of model info failed: Invalid HTTP status 404
2026-09-19 10:28:14,478 ERROR: Loading of model info failed: Invalid HTTP status 404
2026-09-19 10:28:14,479 ERROR: Loading of model info failed: Invalid HTTP status 404
2026-09-19 10:28:14,479 ERROR: Loading of model info failed: Invalid HTTP status 404
2026-09-19 10:28:14,479 ERROR: Loading of model info failed: Invalid HTTP status 404
2026-09-19 10:28:14,479 ERROR: Loading of model info failed: Invalid HTTP status 404
2026-09-19 10:28:14,480 ERROR: Loading of model info failed: Invalid HTTP status 404
2026-09-19 10:28:14,480 ERROR: Loading of model info failed: Invalid HTTP status 404
2026-09-19 10:28:14,491 ERROR: Loading of models failed: Invalid HTTP status 404
```
---
### Author:  [@cgrunenberg](https://discourse.devontechnologies.com/u/cgrunenberg)
#### Post date: [September 19, 2026, 6:08pm UTC](https://discourse.devontechnologies.com/t/ai-settings-cannot-load-model-list/87673/4 "2026-09-19T18:08:22Z")
Does reloading the model list and/or relaunching the app make a difference? And just curious but what’s the use case for these tiny and old Qwen 2.5 Coder models?
---
### Author:  [@SopShuttle](https://discourse.devontechnologies.com/u/SopShuttle)
#### Post date: [September 19, 2026, 7:47pm UTC](https://discourse.devontechnologies.com/t/ai-settings-cannot-load-model-list/87673/5 "2026-09-19T19:47:43Z")
Unfortunately neither reloading the model list or relaunching the app makes a difference.
These Qwen 2.5 Coder models got installed as defaults with the Llama.cpp VSCode plugin, but I don’t particularly need them. Actually I just deleted them to see if that would help and it did not.
The model that was working before was `ggml-org/gemma-4-12B-it-GGUF:Q8_0`, this one works fairly well for file renaming which is mainly what I’m trying to do.
---
### Author:  [@cgrunenberg](https://discourse.devontechnologies.com/u/cgrunenberg)
#### Post date: [September 20, 2026, 7:37am UTC](https://discourse.devontechnologies.com/t/ai-settings-cannot-load-model-list/87673/6 "2026-09-20T07:37:06Z")
The next release will include some improvements regarding model probing. However, for local processing Ollama or LM Studio are highly recommended as they do not need this.
---
### Author:  [@SopShuttle](https://discourse.devontechnologies.com/u/SopShuttle)
#### Post date: [September 20, 2026, 4:12pm UTC](https://discourse.devontechnologies.com/t/ai-settings-cannot-load-model-list/87673/7 "2026-09-20T16:12:15Z")
Thanks, I’ve tried both in the past but llama.cpp seems much faster than either one of those. I found a workaround though, I can start up an individual llama.cpp server for a single model and it seems to work
```auto
> llama-server -m ${GGUF_FILE}
...
llama_server: listening on http://127.0.0.1:8080
```
So I can set the endpoint to that now and it works.